HIDE-Deconv CLI User Guide
1. Overview
HIDE-Deconv is a Python Command Line Interface designed to simplify the process of deconvolution. It serves as an intuitive interface for deconvolution models, providing users with the ability to preprocess single-cell files and conduct statistical post-analyses of deconvolution results. This guide aims to provide an overview of all available commands and the recommended workflow for using HIDE-Deconv.
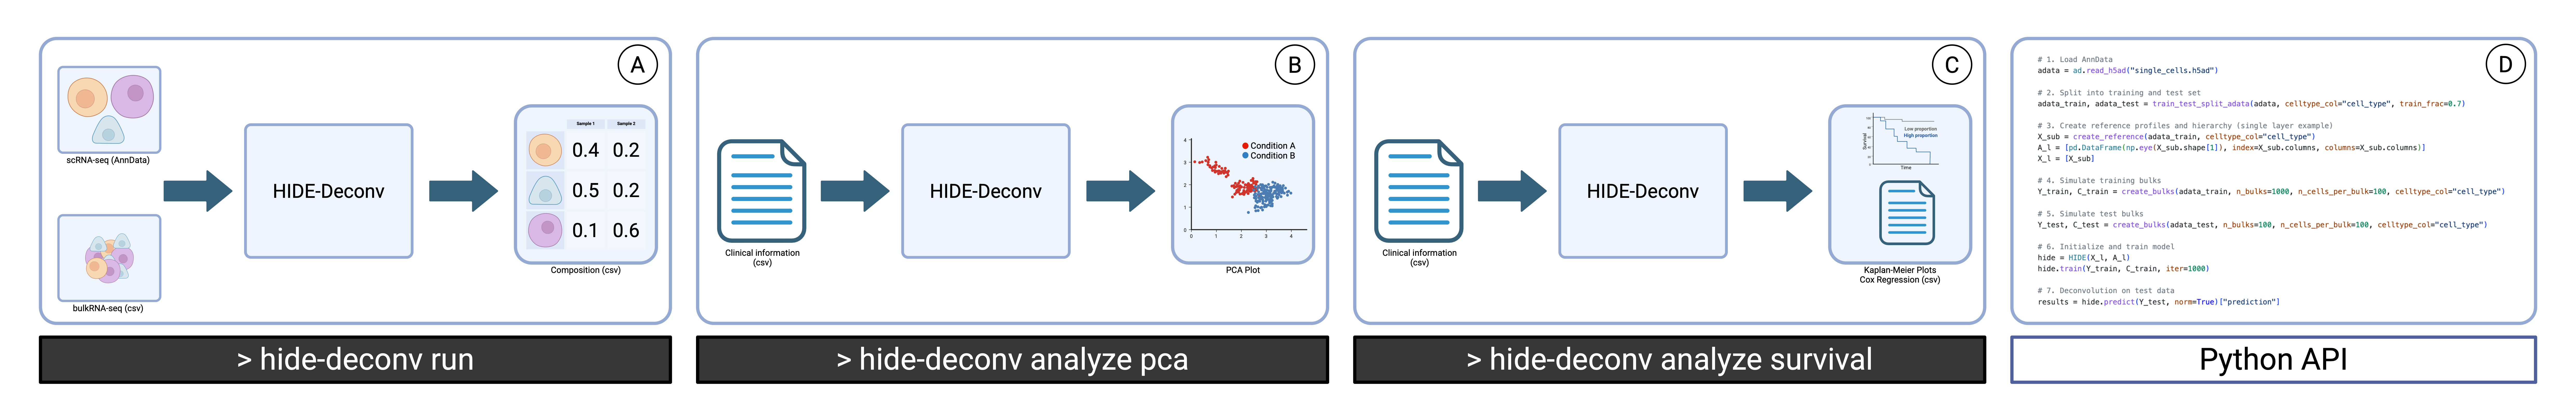
You can read more about the HIDE-deconv model in the preprint uploaded on BioRxiv. Note that the used model is different to our previously published work HIDE.
2. Preliminaries
2.1 Installation
HIDE-Deconv is a standalone Python package distributed via PyPi. To install it, we recommend setting up a virtual environment by typing python3 -m venv .venv in a terminal. HIDE-Deconv is compatible with Python versions 3.12, 3.13, and 3.14.
To activate the virtual environment, use source .venv/bin/activate.
To install the package, use pip install hide-deconv.
For installation on a Windows Computer, these commands can differ.
2.2 Necessary Input Data
To perform deconvolution on bulk RNA-seq data, you need an annotated single-cell dataset, ideally from the same disease or phenotype you intend to deconvolve. The single-cell data should be an AnnData (.h5ad) file. We recommend providing the raw, unnormalized count data.
Bulk RNA-seq data should be provided as a CSV table. The column labels should correspond to the samples measured, and the row names should correspond to the measured genes. The gene labeling type should match the one used in the single-cell file. To utilize the built-in single-cell preprocessing functionality, genes must be labeled as Gene Names. We again recommend using raw, unnormalized count data, but in both cases, the normalization type should be consistent with the single-cell file.
2.3 Additional Input Data
HIDE-Deconv offers built-in functionality for post-deconvolution analyses. However, it requires additional information on cohorts, which will be referred to as the sample sheet in the following document.
The sample sheet should be provided as a CSV table. One column must contain the same IDs as the columns in the bulk RNA-seq data to facilitate the assignment of samples to their corresponding meta information. Meta information should be presented in columns, with individual values for samples as rows.
If you intend to conduct a survival analysis, the column indicating the event must be numerical, with 0 representing the absence of an event and 1 indicating its presence. The column holding the time should either represent the time to the event in the case of an event or the time to the last follow-up in the absence of an event.
3. Standard Workflow
To automate deconvolution as much as possible, HIDE-Deconv offers a guided semi-automated workflow that can be executed using the command hide-deconv run -p <PathToProject>.
Running this command sets up the necessary configuration file and folder structure. After executing the command, the folder path where the project will be initialized will be displayed, and you’ll be prompted to confirm if you want to set up the project there. Subsequently, you’ll be asked to enter the path to the previously mentioned AnnData Single Cell file. Once the file is loaded, you’ll need to select the desired finest-level cell type annotation. These annotations are loaded from the observation entries in the AnnData file. If you want to add further coarser-grained annotations, you can do so in the next step.
Note that higher-level cell type annotations must have a 1:N relationship. This means that one higher-level cell type may map to multiple finer-grained cell types, but each finer-grained cell type must only map to one higher cell type. You can add as many higher-level cell type annotations as you want.
After entering the cell type annotations, you’ll receive information on the number of genes and cells present in the file. You’ll also be prompted to enter the bulk RNA-seq file for deconvolution. An information on the shared gene subset between single cells and bulk samples will be displayed, along with the number of samples.
The next prompts allow you to set up the parameters of the deconvolution, such as the number of used genes and the number of simulated samples.
Once the initialization is complete, you can directly proceed to the preprocessing of the training data and training. After the training is done, you can review the convergence of the model and the results on the simulated data in the figures subfolder in your project location.
The next step is to select the deconvolution model. Currently, only the HIDE model is available. In the future, we will add more models that feature cell type-specific gene regulations and estimate a consensus hidden background profile.
You can access the results of the deconvolution in the results folder, which is located under the subfolder name of the used deconvolution model. Additionally, you can review the error estimates of the models in the files with the err_ prefix.
HIDE-Deconv automatically takes care of accounting for domain transfer between single cell and bulk RNA-seq and necessary library size corrections. These can manually be deactivated by using the --domain_transfer False and --library_size_correction False flag. The libary size correction should be turned off if you work with normalized bulks. If you are using simulated bulks for benchmarking, please read the chapter 8 on benchmarking HIDE-Deconv.
4. Post Deconvolution Analysis
HIDE-Deconv offers several methods for analyzing the deconvolution results. All these commands are accessible within the analyze command subgroup.
4.1 PCA, UMAP and PLS-DA Plotting
To visualize the deconvolution results using PCA, UMAP or PLS-DA, execute the command hide-deconv analyze <pca/umap/plsda> -p <PathToProject>. This command will prompt you to select the desired model and cell type layer from submenus. Additionally, you’ll be asked to specify the path of the sample sheet and the column containing IDs for assigning bulk samples with their corresponding metadata. Finally, you’ll need to select the metadata to divide the results into cohorts. The generated plots will be located in the results folder of the chosen model.
Existing composition datasets can be projected into the PCA, UMAP or PLS-DA calculated from the selected dataset by providing one or more CSV files with --map-others (or -mo). Repeat the option for multiple files, for example hide-deconv analyze pca -p <PathToProject> -mo <PathToComposition1.csv> -mo <PathToComposition2.csv>. The CSV files must use the same cell type labels as the selected composition. The mapped datasets do not influence the calculated components and are shown as additional entries in the plot legend.
4.2 Statistical Differences
HIDE-Deconv also provides an interface to test for statistical differences in the cellular composition of specific cohorts. Based on the number of available cohorts, HIDE-Deconv automatically determines whether to perform a Mann-Whitney-U test between two cohorts or a Kruskal-Wallis test with a post hoc Dunn test to identify the significantly different cohort among multiple cohorts. In all cases, the p-value is adjusted for multiple testing.
To access this feature, you can run the command hide-deconv analyze diff -p <PathToProject>. The results will be stored in the corresponding results folder.
4.3 Visualize differences between two cohorts
For two cohorts, HIDE-deconv is able to run a Mann-Whitney-U test on all cell type layers and visualize them afterwards as a hierarchical heatmap.
The feature can be invoked by hide-deconv analyze hdiff -p <PathToProject>
4.4 Survival Analysis and Cox Regression
To investigate the impact of specific cell types on patient survival, HIDE-Deconv offers a survival analysis command. Before executing this command, it’s crucial to ensure that both the censoring time and the time to event are included in a single column in the sample sheet. The column detailing the event status should contain numerical values, with 0 representing no event and 1 indicating an event. Additionally, the command allows for the inclusion of various covariates (press space to select the covariates in the list, press enter to continue) in the Cox Model. For cell types that significantly influence patient survival, a Kaplan Meier Curve is automatically generated. The user must first specify whether the patients should be divided into samples based on the mean, tertiary, or quartile cell type expression. Furthermore, p-values are corrected for multiple testing, and the resulting tables and plots are saved in the corresponding results folder.
To execute the command, use the following syntax: hide-deconv analyze survival -p <PathToProject>
Additionally the command has certain flags, that can be turned on, that will change the resulting Kaplan Meier plots for significant cell types:
- --risk_table True adds a risk table below the figure
- --censors True will add marks for censored patients to the plot
- --median_surv True will add dashed lines at 50% survival probability
4.5 Partial least squares discriminant analysis
A common alternative to PCA and UMAP is PLS-DA, which is also included in HIDE-Deconv. The command hide-deconv analyze plsda -p <PathToProject> will perform a PLS-DA (to be more specific a PLS2-DA) and save the score, vip and loading plot.
4.6 Visualizing sample compositions as scatterplot
HIDE-Deconv provides a command that plots cell-type abundances as scatterplot. Furthermore the command allows to renormalize the estimated composition to certain cell-types, for example, if you want to compare only changes in immune cell populations without the epithelial compartmenet. If a sample sheet is provided, the points are colored by cohorts.
To use the command, use the following syntax: hide-deconv analyze scatter -p <PathToProject>
4.7 Benchmarking against known compositions
If you have ground truth cell proportions, HIDE-Deconv offers a command that calculates various benchmarking metrics, such as correlation coefficients or RMSE estimates. The ground truth data must be provided as a CSV table, with column names representing sample names and row names representing cell types. It’s important to note that all models produce proportions, which naturally sum to 1. The resulting benchmark results are stored as both a table and a plot in the corresponding results directory. Ensure that the cell type names used in the ground truth data match those used in the deconvolution process.
To invoke the command, use the following syntax: hide-deconv analyze benchmark -p <PathToProject>.
4.8 Visualizing relevant genes
HIDE-Deconv also provides a command that visualizes the most relevant genes for deconvolution as a clustered heatmap. The command can be invoked by hide-deconv analyze genes -p <PathToProject>. After selecting the project, the cell type layer and the number of genes to display, the resulting markermap will be saved in the corresponding results folder.
4.9 K-means clustering of compositions
HIDE-Deconv also provides a command that clusters the cellular compositions with k-means and saves the cluster assignment and a PCA plot. Optionally a sample sheet can be selected so that points are colored by cohorts.
To run the command, use the following syntax: hide-deconv analyze kmean -p <PathToProject>.
4.10 Identification of compositional clusters (alternative to K-means)
HIDE-Deconv provides an alternative clustering command that allows you to identify clusters of similar cell type composition. These clusters are stored in a format that makes them easy to use as a sample sheet for, for example, difference analysis. Additionally, the command generates a UMAP and PCA plot with the assigned clusters color-coded. In comparison to k-means it is not necessary to specify the number of clusters beforehand.
To run the command, use the following syntax: hide-deconv analyze cluster -p <PathToProject>
5. Single Cell Related Commands
HIDE-Deconv, which utilizes the AnnData file format for single-cell data, offers specific functions to enhance accessibility for non-programmers when working with this file type.
5.1 Inspect AnnData file
This command provides an overview of a selected AnnData file. It displays the total number of genes and cells, as well as all entries in the observations and variables.
To use this command, you can invoke it with the command line options hide-deconv anndata inspect. This will prompt you to select the desired AnnData file path and then show the information in the terminal.
5.2 Subset AnnData file
Single cells downloaded from large repositories often exhibit multiple phenotypes. This command enables you to subset the AnnData file to a specific observation. Select the desired observation and then input all the permissible values for it by separating them with spaces. Pressing enter will save the processed file at the same location as the original AnnData file.
To execute the command, use the following syntax: hide-deconv anndata subset
5.3 Add higher cell type Annotations
HIDE-Deconv enables users to run the deconvolution on multiple cell type hierarchies. To add these hierarchies, each single cell in the AnnData file needs annotations on all cell type levels. This can either be achieved by directly annotating the single cells on multiple resolutions in e.g. Seurat. However, it features a command, that allows you to easily group cell types together.
To achieve this, first run the command hide-deconv anndata add-annotation and select the AnnData single cell file and the observation containing your finest grained cell type annotations. HIDE-deconv will then create a template csv table at the location of the AnnData file. Leave the terminal window open and separately open the created template file in an editor.
The file will look like this
| celltype_sub | celltype_sub |
|---|---|
| CD4-T cell | CD4-T cell |
| CD8-T cell | CD8-T cell |
| B cell | B cell |
The left column contains the cell type annotations at the finest level. Do not edit anything in this column, as HIDE-deconv uses this as a reference to. The right column can be edited to contain the hierarchy you want.
| celltype_sub | celltype_minor |
|---|---|
| CD4-T cell | T cell |
| CD8-T cell | T cell |
| B cell | B cell |
If you want to add more levels, just add them to the file.
| celltype_sub | celltype_minor | celltype_major |
|---|---|---|
| CD4-T cell | T cell | Lymphoid |
| CD8-T cell | T cell | Lymphoid |
| B cell | B cell | Lymphoid |
Save the file and switch back to the terminal window. After entering y, HIDE-deconv will load the edited hierarchy, create the corresponding observations in the AnnData file and save it at the same location as the original AnnData file.
5.4 Visualization of single cells
HIDE-Deconv provides a command line interface to scanpy's UMAP plot function. To execute this, type in the command hide-deconv anndata umap, select the AnnData file and the observation, that will be used for coloring the single cells. The plot will be stored at the same location as the AnnData file.
5.5 Preprocessing of single cells
Preprocessing single cell data often improves deconvolution results. Therefor HIDE-deconv offers a separate pipeline, that applies our standard preprocessing to a given AnnData file. It is important to note, that this pipeline was set up for raw count human single cell data and only works with Gene Names. The following steps are performed: 1. Removal of celltypes with not enough single cells (Standard Threshold: 100 cells of one type) 2. Removal of cells with low gene counts (Standard Threshold: 100 counts per cell) 3. Removal of cells with extremely high gene counts (Standard Threshold: 5000 counts per cell) 4. Removal of cells with high amounts of mitochondrial gene expression (Standard Threshold: cells with more than 5 percent mitochondrial gene expression) 5. Removal of cells with high haemoglobine gene expression (Standard Threshold: cells with more than 5 percent haemoglobine gene expression) 6. Removal of cells with high MALAT1 gene expression (Standard Threshold: MALAT1 expression over 99 percentile) 7. Removal of genes that are only expressed in a few cells (Standard Threshold: gene must be expressed in at least 10 cells)
Each of the thresholds can be adjusted before executing the preprocessing pipeline. Keep in mind, that these thresholds should be chosen depending on the specific dataset and can lead to worse results, if chosen incorrectly.
To run the preprocessing pipeline, use the command hide-deconv anndata preprocess
5.6 Converting a MTX file to AnnDat file
Some single cell experiments are stored as mtx files, to facilitate usage of this datatype, HIDE-Deconv provides a command, that converts the mtx file and the corresponding barcode and feature file to an AnnData file. Note: currently cell type annotations have to be done manually afterwards.
To invoke the command, run hide-deconv anndata mtx
6. Bulk related commands
HIDE-Deonv provides multiple commands to perform various operations on bulk RNA seq files without the need for writting code.
6.1 Visualizing bulk data
The package provides methods for visualizing the bulk RNA seq data as either UMAP or PCA plot. Additionally by providing a sample sheet, samples in the plots can be annotated by clinical metainformation.
To invoke the command, type in hide-deconv bulk <umap/pca>
6.2 Subsetting bulks
In some cases you might want to exclude certain samples from the deconvolution. This can be the case, if the bulk data file for example contains measurements from multiple tissues. This can be done by using the hide-deconv bulk subset command. Here you need to first select the bulk data file to be subsetted and a sample sheet containing the cohort column, you want to use to subset. After selection of the cohort column, select the value you want to keep by pressing Space. To apply your selection, press Enter.
6.3 Inspecting clusters in bulk data
HIDE-Deconv provides a command that allows you to identify clusters of similar bulk samples. These clusters are stored in a format that makes them easy to use as a sample sheet for, for example, difference analysis. Additionally, the command generates a UMAP and PCA plot with the assigned clusters color-coded.
To run the command, use the following syntax: hide-deconv bulk cluster
6.4 Differential Gene Expression Analysis
To further support analyses related to bulk deconvolution projects, HIDE-deconv implements an interface to the PyDeSeq2 implementation of DeSeq2.
To invoke the command, run hide-deconv bulk deg
6.5 Converting a MTX file to csv table
Often bulk RNA files are not stored as csv tables, but rather as mtx files. Therefor HIDE-Deconv provides a command, that converts the mtx file and the corresponding barcode and feature file to a compatible csv table
To invoke the command, run hide-deconv bulk mtx
7. Sample Sheet related commands
7.1 Merging cohorts
In case the sample metainformation is to fine grained, or you want to combine certain cohorts in one, HIDE-deconv provides a command, that enables merging them directly. Depending on the type of information you can either use hide-deconv cohort combine for categorical information or hide-deconv cohort combine --numerical for numerical data.
In both commands you first have to select the sample sheet and the column that should be merged. If it is categorical data you have to specify how many new cohorts should be assigned, name the column and name each cohort and select the merged values by pressing space. Accept the selection by pressing enter. For numerical data you can choose to either split the data by the mean or median value or by a fixed number. The merged columns will be labeled either as high or low.
7.2 Plotting Kaplan Meier Curves
HIDE-deconv contains a basic command for plotting Kaplan Meier curves for different cohorts based on the sample sheet. The column detailing the event status should contain numerical values, with 0 representing no event and 1 indicating an event.
To run the command, use the following syntax: hide-deconv cohort km.
Additionally the command has certain flags, that can be turned on:
- --risk_table True adds a risk table below the figure
- --censors True will add marks for censored patients to the plot
- --median_surv True will add dashed lines at 50% survival probability
8. Benchmarking HIDE-Deconv
HIDE-deconv contains a simple command, that splits a given AnnData single cell file into a train and test set, and generates artifical bulks for testing with a known composition. The percentage of cells to remain in the training set can be chosen beforehand.
To run the bulk simulation command, use the following syntax: hide-deconv simulate
Simulated validation bulks without an explicitly simulated domain shift should be applied to the model with the domain transfer and library size correction feature turned off. This can be done by setting the domain transfer flag to false: hide-deconv run --domain_transfer False --library_size_correction False.
After training the model and deconvolving the simulated bulks, it is possible to calculate various deconvolution benchmark metrics by using hide-deconv analyze benchmark -p <PathToProject>
9. License
HIDE-deconv is licensed under the MIT license.
10. Contributing, Bugs, Feature Requests
If you found a bug or have specific feature requests, we encourage you to either contact us or read the Contributing guide on GitHub.
11. Contact
For questions, support or scientific collaboration feel free to contact us per Email: - Dennis Voelkl: dennis.k.voelkl(at)uib.no - Franziska Goertler: Franziska.Gortler(at)uib.no